How to Build a Smarter Podcast Content Classification Workflow
0m | Oct 10, 2026Finding the right podcast episode is not always easy. A listener might search for a discussion about personal finance, yet receive unrelated business interviews or general economic news. As podcast libraries grow, organizing episodes by meaningful topics becomes increasingly important. Accurate classification helps listeners discover relevant conversations while making large content collections easier to manage.
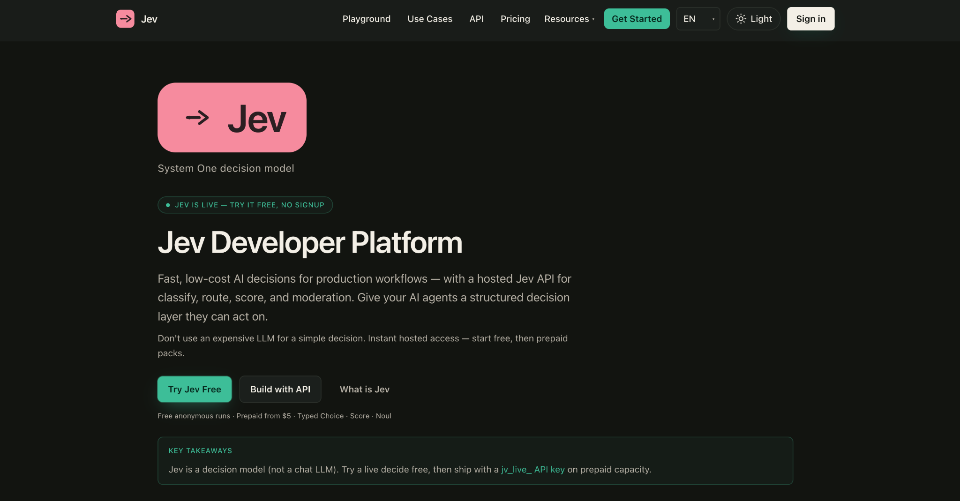
Traditional classification often depends on manual tagging or basic keyword rules, which can struggle with overlapping subjects and inconsistent descriptions. Developers exploring more structured approaches can use the Jev Developer Platform to examine how AI-driven classification decisions work. Its interactive workbench allows users to test decision scenarios before considering API integration. Understanding these methods can help developers build podcast discovery workflows that remain accurate, manageable, and easy to evaluate.
Why Podcast Classification Becomes Difficult
A single podcast episode can cover several subjects. An interview about artificial intelligence might also discuss education, employment, privacy, and government regulations. Assigning only one broad category can hide useful information, while assigning too many labels can make the classification system confusing.
Manual tagging presents another challenge. Different editors may describe similar episodes using different categories. One might label an interview "Technology," while another selects "Artificial Intelligence." Both could be reasonable, but inconsistent terminology makes searching and organizing content more difficult.
Keyword-based rules offer a straightforward alternative. However, matching individual words does not always reveal the actual subject. An episode mentioning "investment" briefly might focus primarily on career development rather than personal finance.
Reliable classification requires understanding the main subject, following consistent rules, and reviewing uncertain decisions.
Prepare Podcast Metadata Before Classification
Before introducing automated classification, developers need reliable episode information. Poorly written descriptions or incomplete transcripts can lead to incorrect categories regardless of the method used.
Start by collecting essential metadata, including the episode title, description, publication information, and available transcript excerpts. The information should reflect the actual recording rather than promotional language.
For example, consider an episode titled "Building Better Habits." Its title alone provides limited context. However, a description explaining that the guest discusses sleep routines, workplace stress, and daily exercise offers much stronger classification evidence.
A simple preparation process involves:
- Collect episode information. Gather verified titles, descriptions, and relevant transcript excerpts.
- Remove unnecessary text. Exclude unrelated promotions, repeated introductions, and irrelevant formatting.
- Define topic categories. Create a consistent set of labels such as Health, Education, Business, and Technology.
- Document category boundaries. Explain when each label should or should not apply.
- Select test examples. Include both straightforward episodes and conversations covering multiple subjects.
This preparation makes later decisions easier to evaluate and reduces avoidable classification errors.
Build a Structured Classification Workflow
Once the metadata and categories are ready, developers can design a workflow that assigns a primary topic to each episode. The process should separate content collection, decision-making, and quality review.
Step 1: Define the Classification Rules
Begin with a small collection of clearly distinguished categories. Each category should include a short description explaining its intended meaning.
For example, a podcast discussing software development could belong under Technology, while an episode explaining household budgeting would fit Personal Finance.
When an episode covers multiple topics, determine whether the primary category should represent the main discussion, the listener's likely search intent, or another documented editorial rule.
Step 2: Test an API-Based Decision
Instead of building every classification rule manually, developers can evaluate structured decision models using existing podcast descriptions.
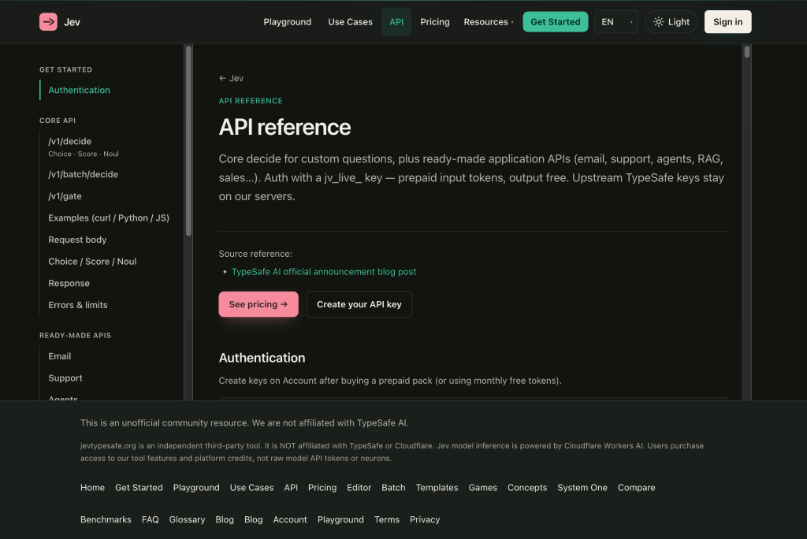
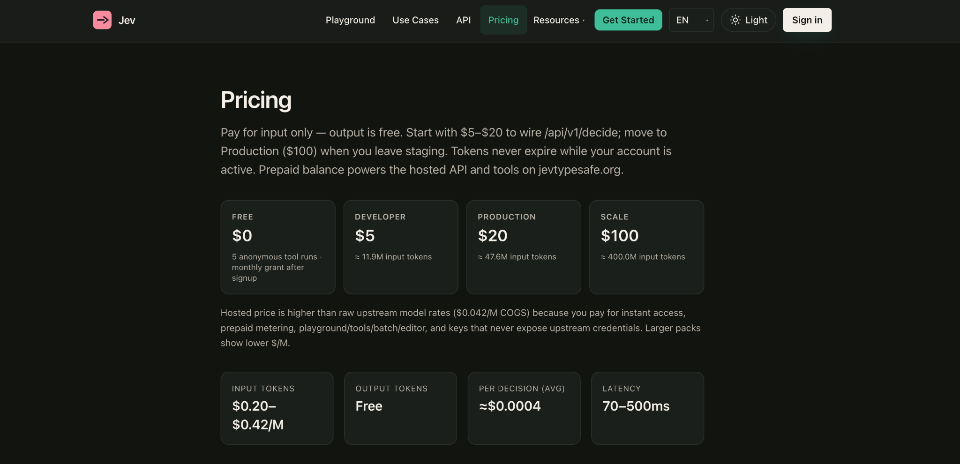
The Jev api provides a hosted decision endpoint that accepts contextual input and defined questions. Its Choice capability can select among predefined topic labels, making it relevant to classification experiments.
For a podcast episode, the input could contain its verified title and description, while the question specifies available categories and asks for the primary subject.
The returned decision includes a selected label and probability information that developers can examine before accepting the result.
The website also provides an interactive workbench with a Content Tagging scenario. Developers can explore this type of decision and review the API documentation before implementing their own workflow.
Step 3: Review Uncertain Results
Automated classifications should not automatically become permanent metadata. Episodes covering several subjects may produce ambiguous results, particularly when descriptions provide limited context.
A review process can flag cases where probability distributions are close, category definitions overlap, or the returned label conflicts with known episode information.
For example, an interview about the business implications of AI might reasonably fit both Technology and Business. A human editor should examine the central discussion before selecting the final category.
The purpose of automation is to support consistent decisions, not eliminate editorial judgment.
Measure Classification Accuracy
A classification workflow should be evaluated before it is applied to a large podcast collection. Developers can begin with a manually reviewed sample containing episodes from every supported category.
Compare automated labels against the reference classifications and identify recurring disagreements. Accuracy provides one useful measure, but it should not be the only evaluation criterion.
Consider these questions:
- Are frequently used categories receiving appropriate labels?
- Do similar episodes receive consistent classifications?
- Are overlapping topics creating predictable errors?
- Does the system correctly distinguish the main discussion from passing mentions?
- Can editors easily identify and correct questionable results?
For collections with uneven category sizes, examine precision and recall for individual categories rather than relying entirely on overall accuracy.
Document the mistakes, adjust category definitions, and repeat the same tests. Consistent evaluation helps determine whether changes actually improve the workflow.
Improve Podcast Discovery Through Better Organization
Classification becomes especially useful when its results support podcast search and browsing. Meaningful labels can help developers create topic collections, filter episode libraries, and organize content beyond broad show-level categories.
Imagine a podcast series covering entrepreneurship. Some episodes discuss marketing strategies, others focus on hiring employees, and several explore business financing.
If every episode receives only the Business label, listeners must examine individual descriptions to locate relevant discussions. More specific topic classifications could help organize episodes into useful collections.
However, assigning labels does not automatically improve search rankings. A discovery system must still consider text relevance, metadata quality, and the actual needs of listeners.
Developers should therefore test classification as one component of a broader discovery workflow rather than treating it as a replacement for search technology.
Explore and Validate the Workflow
Before introducing structured decisions into a production system, developers should experiment with representative podcast descriptions and carefully defined categories.
Start with a familiar episode, determine its expected classification, and compare that judgment with the automated result. Then test more complicated descriptions that contain overlapping subjects or insufficient information.
Developers interested in exploring this approach can visit the Jev Developer Platform and examine its interactive decision examples, including Content Tagging. The workbench provides an opportunity to inspect structured outputs before deciding whether an API-based solution fits their requirements.
These experiments can reveal where automation may be useful and where additional editorial review remains necessary.
A successful implementation should produce understandable decisions, support corrections, and remain consistent as new podcast episodes are added.
Conclusion
Building a better podcast classification workflow begins with accurate metadata, meaningful topic definitions, and consistent evaluation. Automated decisions can assist with repetitive classification tasks, but human review remains essential when subjects overlap or available information is incomplete.
Developers should begin with a small collection of episodes, establish reference classifications, and test different approaches before expanding the system.
By combining structured decisions with clear editorial standards, podcast platforms can create more organized content libraries and help listeners find discussions that better match their interests.